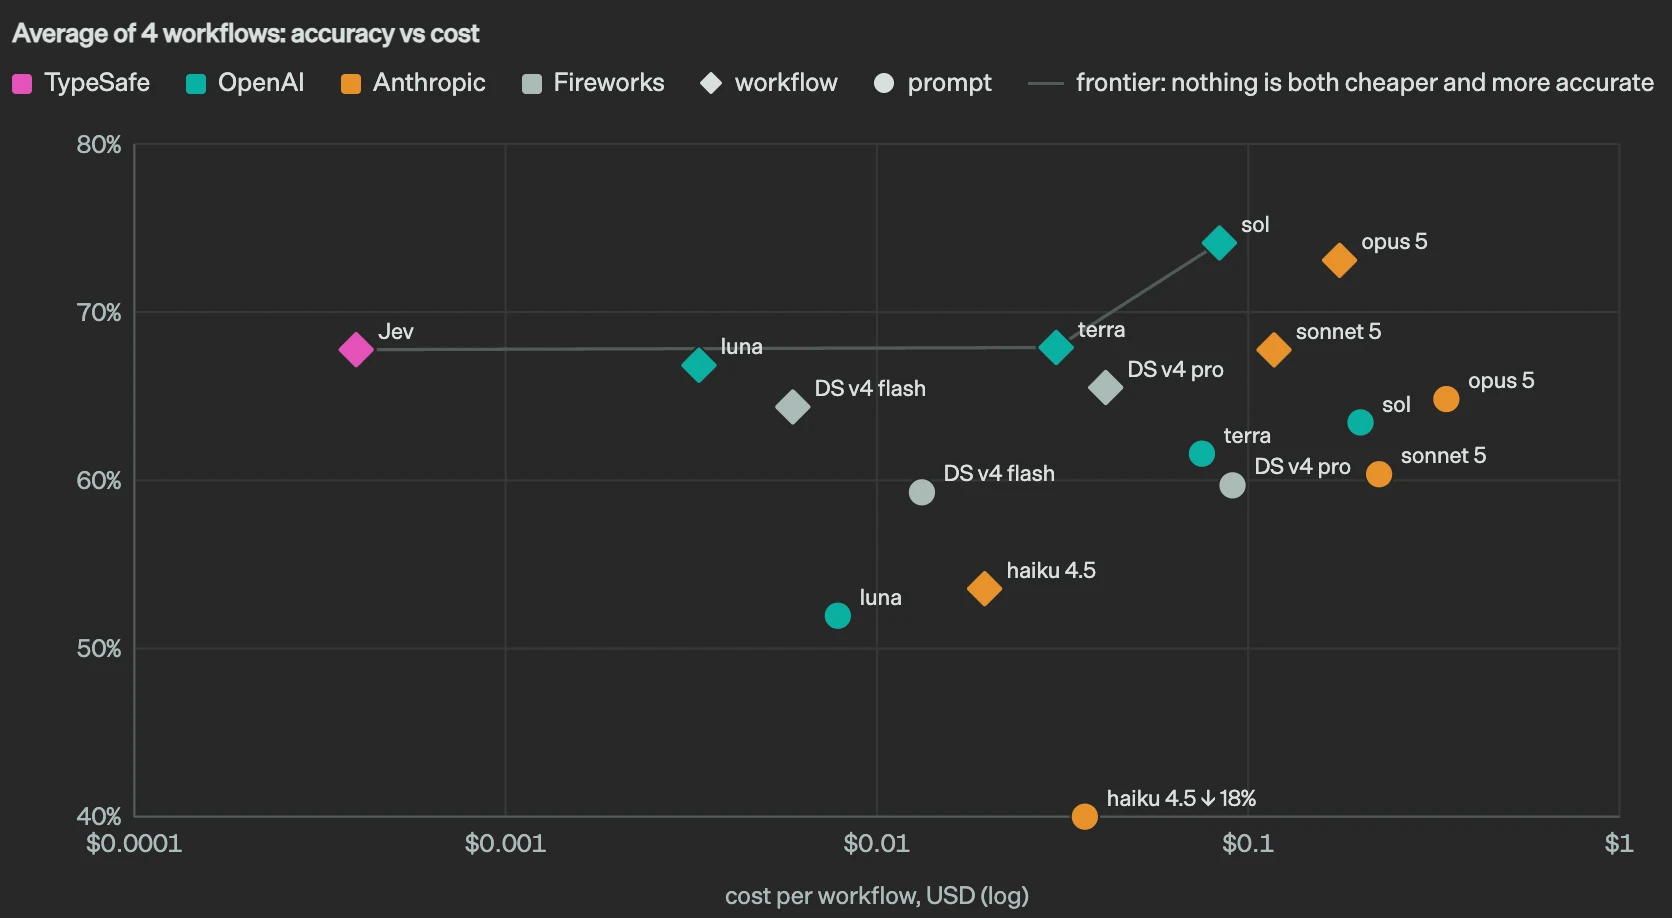
What Jev is, how its typed-decision architecture differs from general LLMs, and what a 300-input emergency-dispatch benchmark revealed about speed, cost, and accuracy.

Image: TypeSafe AI.
Jev recently launched, and its approach to handling large volumes of independent decisions in parallel caught my attention. But does “fast and cheap” also mean accurate?
I built a small Emergency Control Room demo to test it.
TypeSafe AI describes Jev as a System One Model. Unlike a general-purpose LLM that generates open-ended text token by token, Jev receives unstructured application state and returns typed, probabilistic decisions constrained by a schema.
That makes it interesting for classification, routing, scoring, filtering, and prioritization—cases where software needs a decision rather than a paragraph.
The difference is not just that Jev is smaller or faster. It is designed around a different interface and sampling process.
| General-purpose LLM | Jev / System One Model | |
|---|---|---|
| Main objective | Generate useful text for people: answers, code, explanations, or tool calls | Produce calibrated decisions that software can use directly |
| Training approach | Usually RLHF or reinforcement learning with verifiable rewards | TypeSafe describes RLCD: Reinforcement Learning for Calibrated Decisions |
| Sampling | Sequential: generates one token at a time, conditioned on the previous token | Parallel sampler: generates the requested decision outputs in one query |
| Output | Strings that the application must parse and validate | Typed values defined by the application schema |
| Uncertainty | Confidence must usually be requested and may be inconsistent | Probabilities and confidence scores accompany the decisions |
| Best fit | Open-ended, human-facing work | Classification, routing, scoring, filtering, and branching inside software |
In other words, Jev is closer to a probabilistic decision function than to a chatbot. The trade-off is intentional: it gives up open-ended text generation in exchange for predictable structure and lower latency.
A schema can prevent a malformed answer, but it cannot guarantee that the decision is semantically correct. That distinction matters in the benchmark below.
TypeSafe reports 70–500ms end-to-end response time for its workflows. In the company's launch comparison, it reports 3–329 seconds for frontier LLMs, but those figures are vendor-reported and depend on the task, prompt, model, network, and serving setup. They should not be treated as a universal apples-to-apples benchmark.
In my Emergency Control Room run:
TypeSafe lists Jev at $0.042 per 1 million input tokens. It says output tokens are effectively free to meter because Jev returns compact typed decisions rather than long generated passages.
For context, here are standard pay-as-you-go list prices checked in September 2026. This compares token prices only; the models have different capabilities, output formats, and billing rules.
| Model | Input / 1M tokens | Output / 1M tokens | Typical output |
|---|---|---|---|
| Jev | $0.042 | Free to meter* | Typed probabilistic decisions |
| GPT-4.1 mini | $0.40 | $1.60 | Generated text |
| Gemini 3.1 Flash-Lite | $0.25 | $1.50 | Generated text |
| Claude Sonnet 5 | $2.00 | $10.00 | Generated text |
On input price alone, Jev is about 9.5× cheaper than GPT-4.1 mini, 6× cheaper than Gemini 3.1 Flash-Lite, and 48× cheaper than Claude Sonnet 5. That does not mean Jev replaces these models: a prose answer, code generation, or long explanation is a different workload from a typed classification decision.
The app simulates an emergency dispatch center in the city. Each incident is sent to Jev to:
A deterministic policy engine then assigns operational priority. The dashboard streams results onto a map and tracks latency, tokens, estimated cost, accuracy, precision, recall, F1, and a confusion matrix.
The reference labels are never sent to Jev. They are used only afterward to compare the model's decisions with the expected answers.
The dataset contains 50 independently authored and labeled base scenarios, each presented through six neutral reporting contexts. This is an exploratory benchmark, not a production-safety evaluation.
The weakest behavior was not formatting. Jev returned valid typed data for every request.
The problem was abstention.
OUT_OF_SCOPE was explicitly included as a valid choice in the schema, but Jev selected it correctly for only 1 of 24 out-of-scope cases. It often forced unfamiliar inputs into an existing incident category instead of abstaining.
By contrast, it returned NEEDS_REVIEW correctly for all 24 of 24 review cases.
This does not prove a universal limitation of Jev. It shows that abstention behavior must be tested explicitly for each schema and dataset rather than assumed.
Jev was fast, inexpensive, and operationally clean. Its typed-decision interface removed parser failures and made it straightforward to connect the model to ordinary application code.
The core trade-off is now clearer:
But this experiment also produced the most important lesson:
300/300 valid outputs—but only 57% fully correct. Structured output is not the same as a correct decision.
Continue exploring similar topics

Turn a Mac at home into a private personal server you can access from an iPhone with Tailscale, SSH, and tmux—without router port forwarding.
OpenEZ indexes code and documentation into local SQLite, builds a symbol graph, and exposes bounded retrieval, relationship traversal, and durable project memory through MCP for AI coding agents.
Agent DevKit is a lightweight workflow for reliable AI-assisted development: focused skills, approval-gated planning, systematic debugging, an Obsidian-friendly source-grounded wiki, and optional OpenEZ code intelligence.
A practical guide to MCP: what it is, how it differs from REST, how to design reliable tools, how to build a minimal MCP server, and how apps or AI agents connect to it in production.
A practical look at Moonshot AI's Kimi K3, why it is trending, how its benchmarks compare, and where it may or may not be useful today.